

You can prevent content scraping on a WordPress site by trimming your feed, setting bot rules and filing takedowns fast. No single step stops every scraper. A few layers make your site a harder target than the next blog.
We checked each vendor claim against its own documentation in October 2026. We also tested the feed, robots.txt and user agent rules on a WordPress 7.1.3 test site.
This guide explains what scrapers take and how to spot them. You then get six fixes for WordPress, a removal plan for copies, and a plain look at what still gets through.
What Is Content Scraping?
Content scraping is the automatic copying of your pages by a script or bot. The copy is usually posted on another site or fed into another product. It can take your articles, product descriptions, images and prices without asking, and it is the main reason site owners try to prevent scraping. If you want to borrow a layout instead, see how to copy a WordPress site design legally.
Scrapers reach your content in three ways. Some read your RSS feed, some fetch your public pages like a browser, and some copy by hand.
AI training crawlers belong in the second group. Their vendors publish robots.txt names for them. That makes them easier to manage than a hostile scraper.
Not every copy is hostile. Some tools quote you with credit and a link. This guide targets copies made without permission, such as a bulk feed import that republishes your full posts.
Stores feel this too. Product descriptions are easy to lift in bulk, and a copied catalog costs you the work you put into every line.
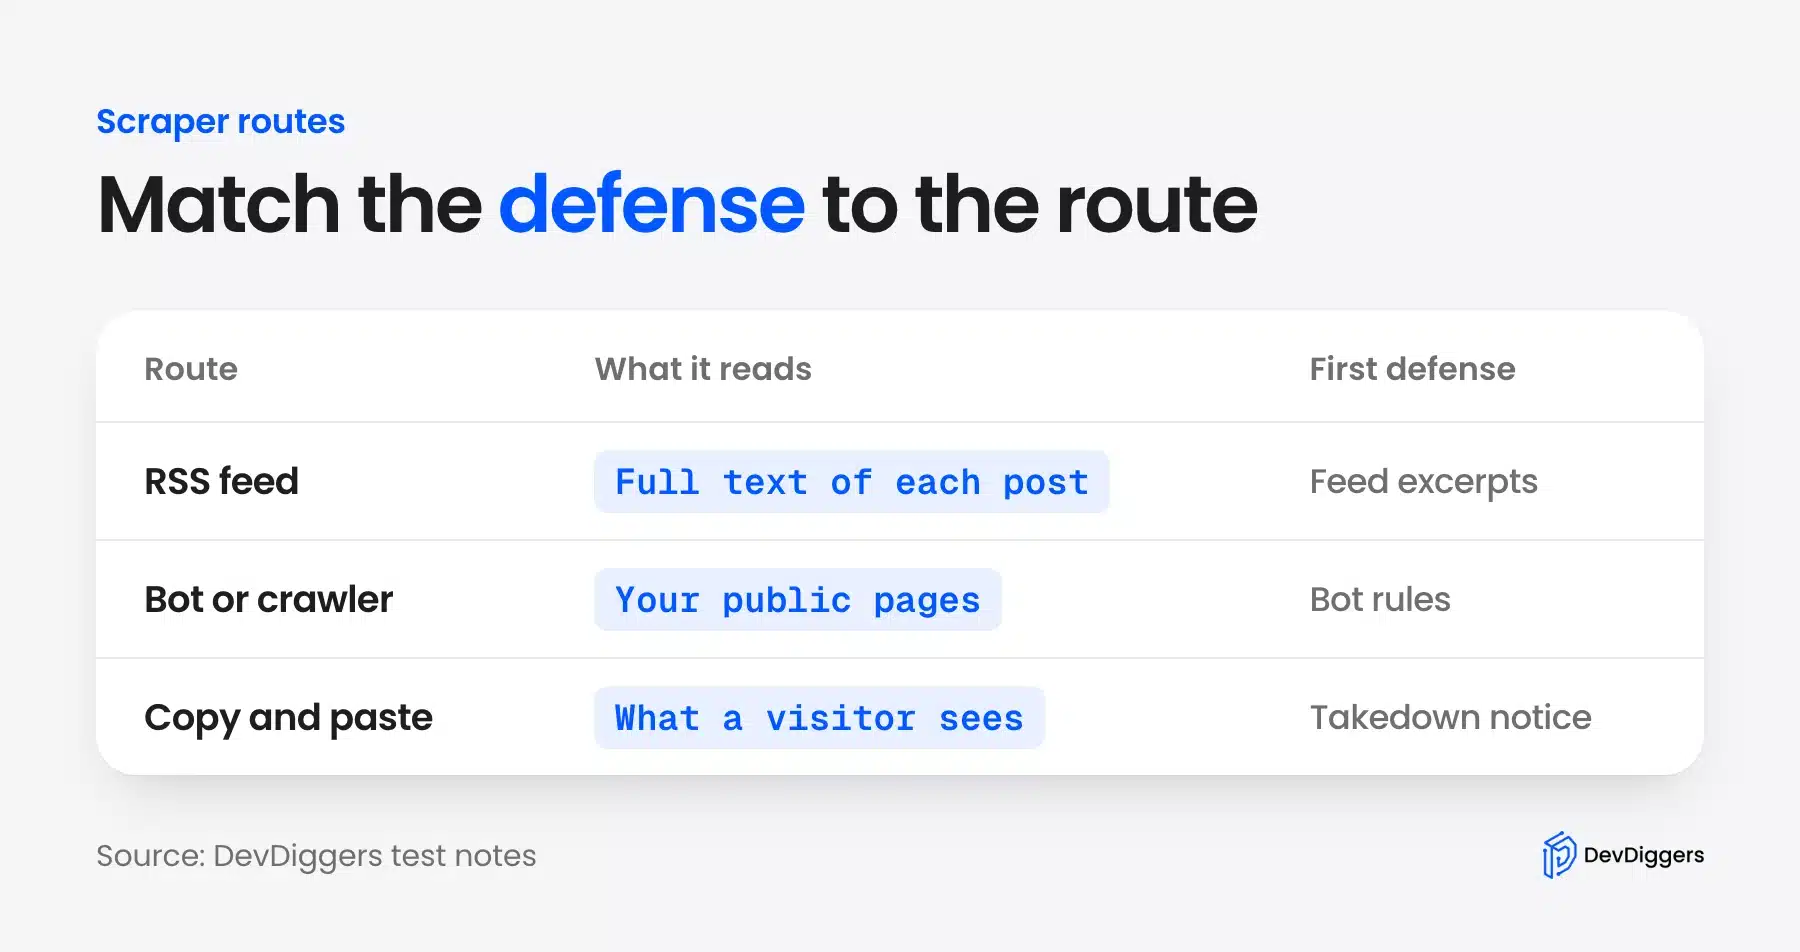
Which route is used decides which defense works. A feed scraper needs a different fix from a bot that loads your pages.
How Can You Tell Someone Is Scraping Your Content?
You can spot scraping by searching for your own sentences, reading your server logs and watching your feed traffic. Paste a distinctive sentence from a post into a search engine in quotes. Then check your logs for visitors that name a bot instead of a browser.
Start with the quoted search, because it costs nothing. If an unfamiliar domain returns your exact sentence, you have found a copy. Pick a sentence with an odd phrase in it, since common phrases match many pages.
Next, open your hosting access logs and look at the user agent column. A name such as Scrapy or a library name is a bot. Browsers send a Mozilla string with a browser version.
An alert is the lazy way to keep watching. Pick one distinctive sentence from each new post and set an alert for it. A new match tells you a copy has appeared.
Write down what you find. Note the copy’s URL, the date you saw it and whether it links back to you. You need that list for the removal steps later in this guide.
6 Ways to Prevent Content Scraping on WordPress
Six fixes help you prevent content scraping on WordPress, from feed settings to edge rules. Show excerpts, add a link back, set robots.txt rules, block named bots, add Cloudflare rules and keep a canonical tag. Each one covers a different route.
Use as many of them as you can.
1. Show Only Excerpts in Your RSS Feed
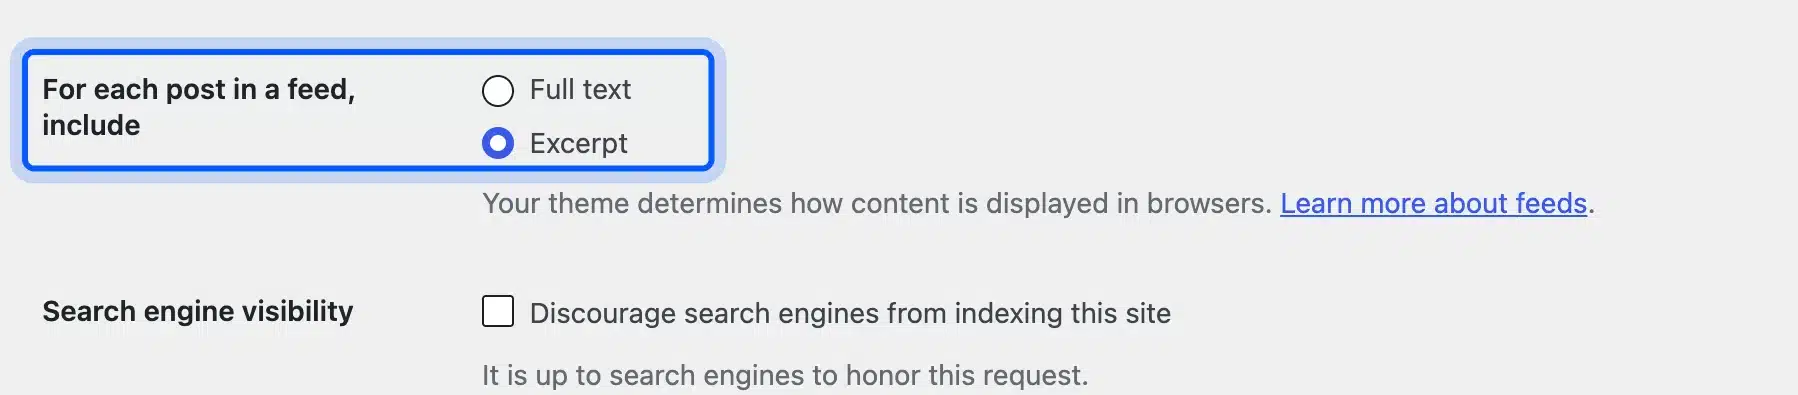
Setting your feed to excerpts stops feed scrapers from receiving whole posts. Go to Settings > Reading and choose Excerpt for the line called For each post in a feed, include. The WordPress documentation lists Full text and Excerpt as the two choices.
On our WordPress 7.1.3 test site, a feed of four posts weighed 13,604 bytes with full text. It weighed 4,096 bytes with excerpts. The scraper receives the opening lines and a link instead of the article.
This fix has a cost. Readers who follow you in a feed reader must click through to read. That is a fair trade for most blogs.
2. Add a Link Back to Every Feed Item
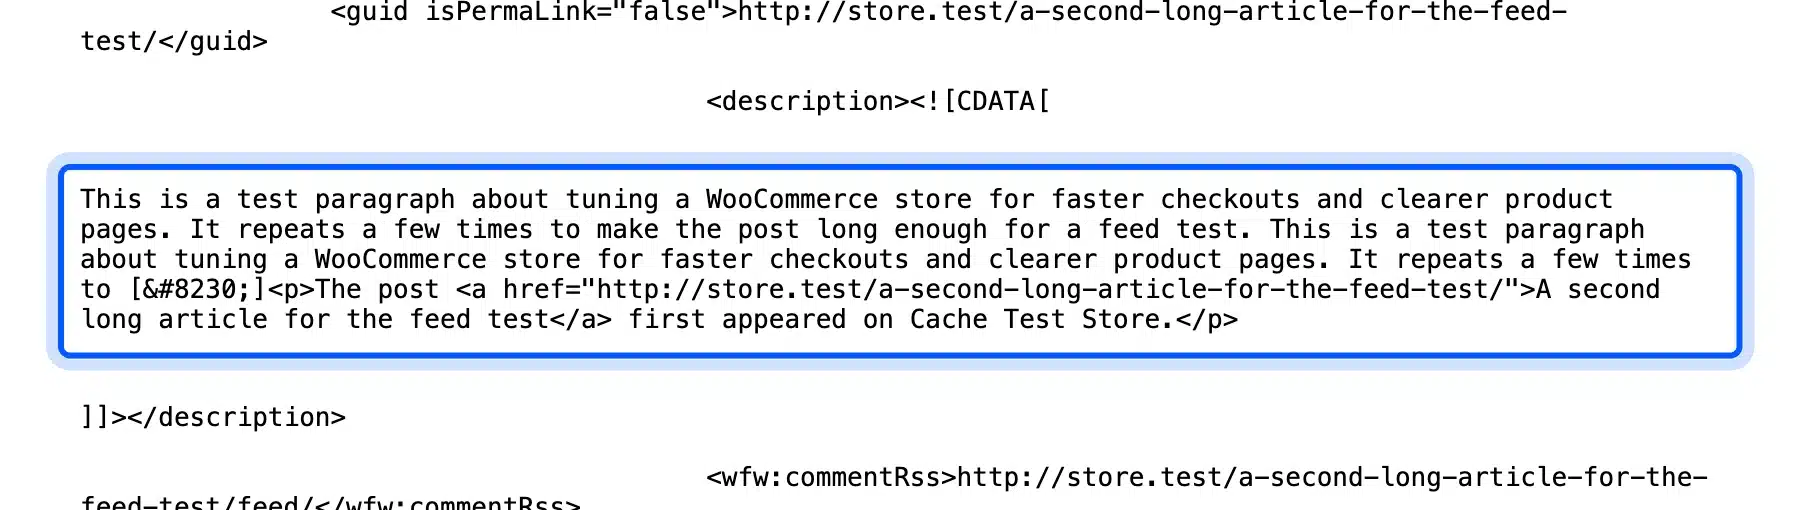
A link back turns a copied feed item into a pointer to your original post. Feed scrapers publish what the feed gives them, and the footer travels with the copy.
The snippet below adds a line with your post title and site name.
Add it to a code snippets plugin or your child theme’s functions.php file:
function ddexample_feed_footer( $content ) {
	$link = '<a href="' . esc_url( get_permalink() ) . '">' . esc_html( get_the_title() ) . '</a>';
	$site = esc_html( get_bloginfo( 'name' ) );
	return $content . '<p>' . sprintf( 'The post %1$s first appeared on %2$s.', $link, $site ) . '</p>';
}
add_filter( 'the_excerpt_rss', 'ddexample_feed_footer' );
add_filter( 'the_content_feed', 'ddexample_feed_footer' );
We ran this on our test site. Every feed item ended with the footer, in both the excerpt and the full text setting.
A scraper that strips HTML will drop the link. Even so, the footer costs nothing and catches the lazy ones.
3. Block AI Crawlers in robots.txt
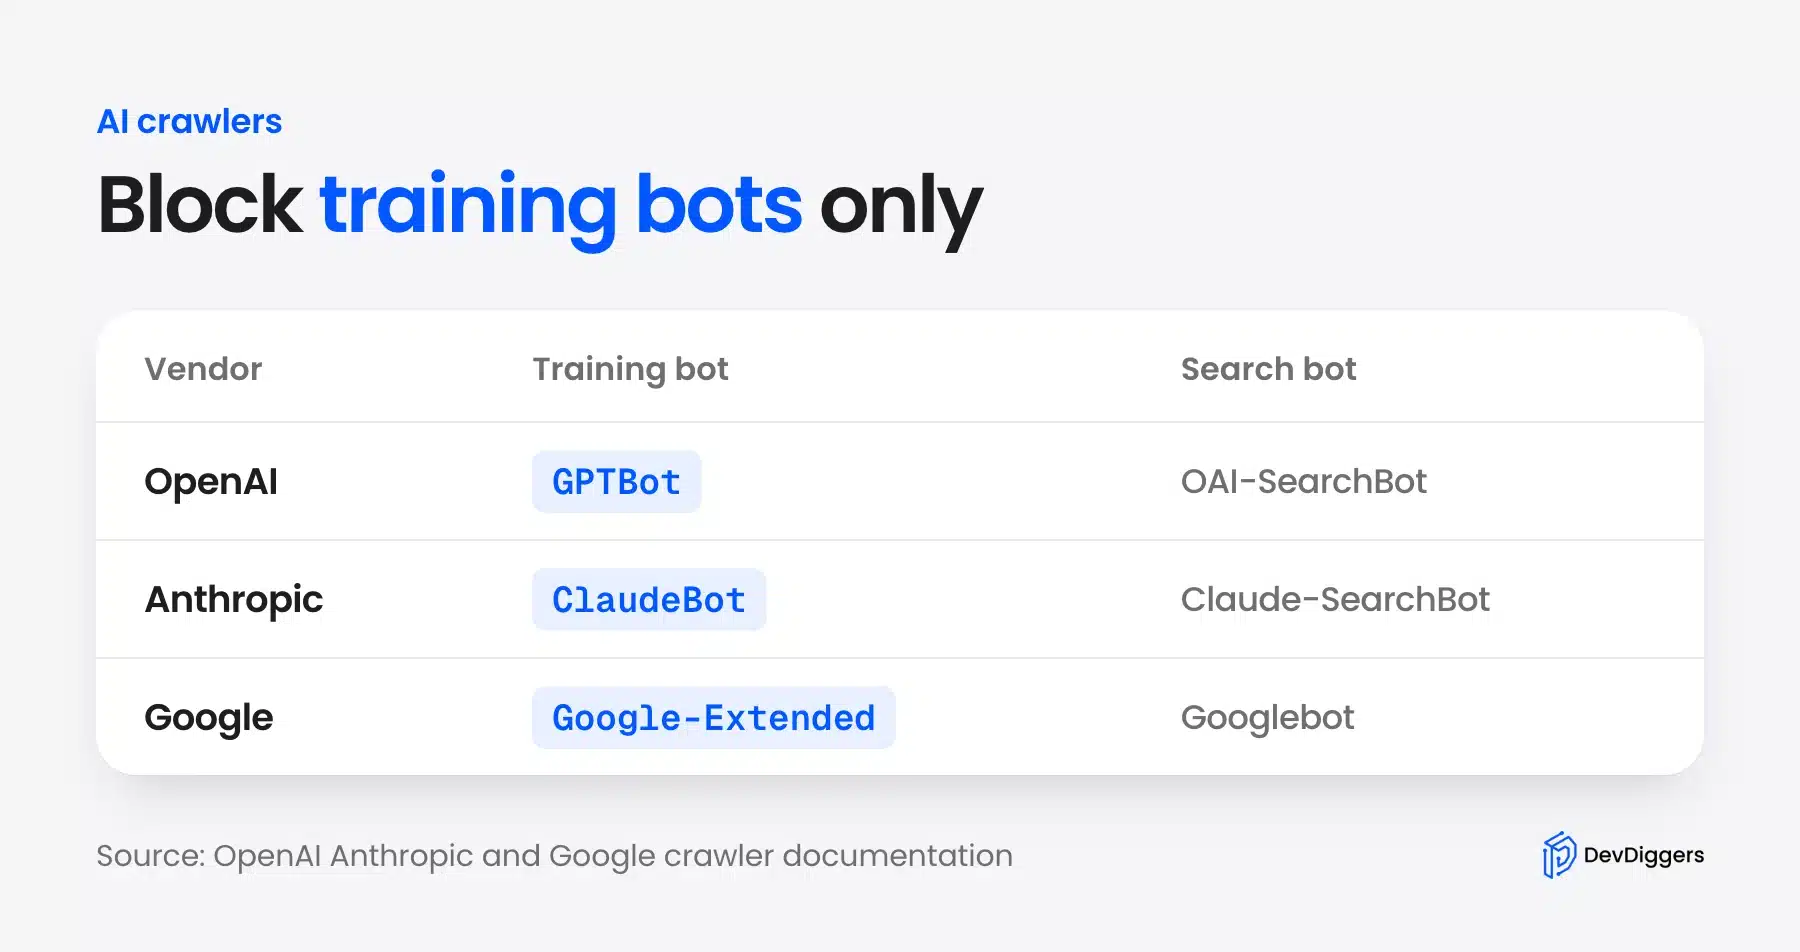
You can block AI crawlers that train models by naming them in robots.txt. Each vendor runs separate bots for training and for search. Block the training bot and keep the search bot if you still want to be cited. A free tool can show which AI bots your robots.txt blocks right now.
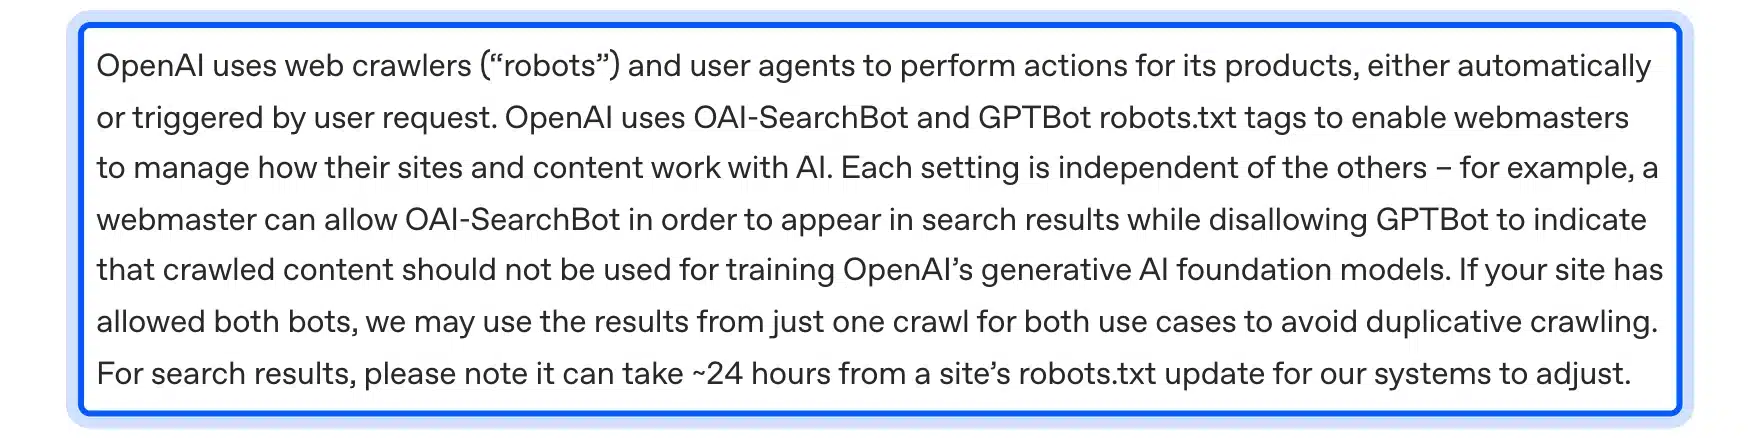
OpenAI’s documentation says each setting is independent. It gives the example of allowing OAI-SearchBot while disallowing GPTBot. That keeps your content out of training.
If you worry about losing AI citations, read our guide on GEO vs SEO. It explains how AI search differs from classic search.
Anthropic runs three crawlers. ClaudeBot collects content that could train models. Claude-User fetches pages for a person’s question, and Claude-SearchBot supports search results.
Google uses a robots.txt token called Google-Extended. Google’s crawler page says it does not affect inclusion in Google Search.
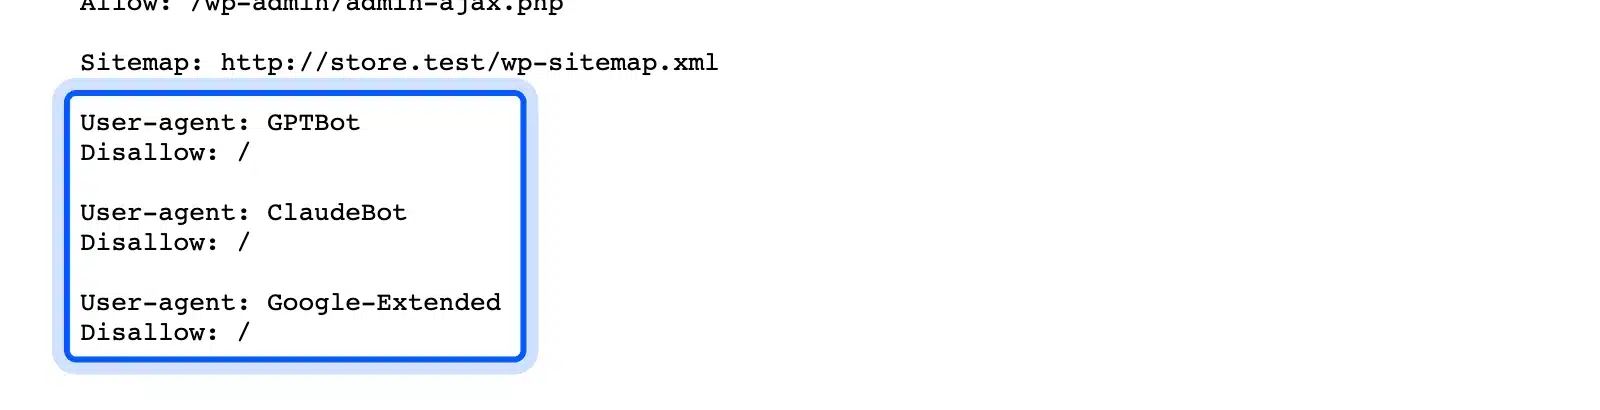
WordPress builds a virtual robots.txt file when no real file exists. Add rules to it with the robots_txt filter:
function ddexample_robots( $output ) {
	$bots = array( 'GPTBot', 'ClaudeBot', 'Google-Extended' );
	foreach ( $bots as $bot ) {
		$output .= "\nUser-agent: " . $bot . "\nDisallow: /\n";
	}
	return $output;
}
add_filter( 'robots_txt', 'ddexample_robots' );
Open yourdomain.com/robots.txt after saving. On our test site the three blocks appeared under the default rules.
Treat this as a request. RFC 9309 says robots.txt rules “are not a form of access authorization”.
OpenAI also notes that robots.txt rules may not apply to ChatGPT-User. That agent acts on a person’s request.
Changes are not instant. OpenAI says its search systems can take about 24 hours to adjust after a robots.txt update.
4. Block Named Scraper Bots at the Server
A server rule can block content scraping by refusing bots that name themselves. It works when the bot sends an honest user agent. It does nothing against one that pretends to be a browser.
This snippet returns a 403 page for three names. It runs early on every request:
function ddexample_block_bots() {
	$agent = isset( $_SERVER['HTTP_USER_AGENT'] ) ? sanitize_text_field( wp_unslash( $_SERVER['HTTP_USER_AGENT'] ) ) : '';
	if ( $agent && preg_match( '/GPTBot|ClaudeBot|Scrapy/i', $agent ) ) {
		wp_die( 'Access denied.', 'Forbidden', array( 'response' => 403 ) );
	}
}
add_action( 'init', 'ddexample_block_bots', 1 );
Choose the names from your own logs. Do not add a search engine to the list.
We tested it on our test site with six requests. A normal browser name returned 200. The GPTBot, ClaudeBot and Scrapy names each returned 403.
A request that named itself MyHarvester returned 200. So did one that only claimed to be Googlebot.
That is the limit of this method. The rule only stops the names you listed.
The same idea of refusing repeat offenders appears in limiting login attempts in WordPress. Both rely on stopping a request early.
5. Use Cloudflare Bot Rules
Cloudflare can apply bot rules to your whole domain. Its dashboard has an AI bot policy and rules that cap requests per visitor. Both work without changes to your WordPress files.
Cloudflare’s documentation says to go to Security Settings > Configure AI bot policies. It offers three presets: Search, Agent and Training. Each can be set to block on all pages, block on pages with ads, or allow.
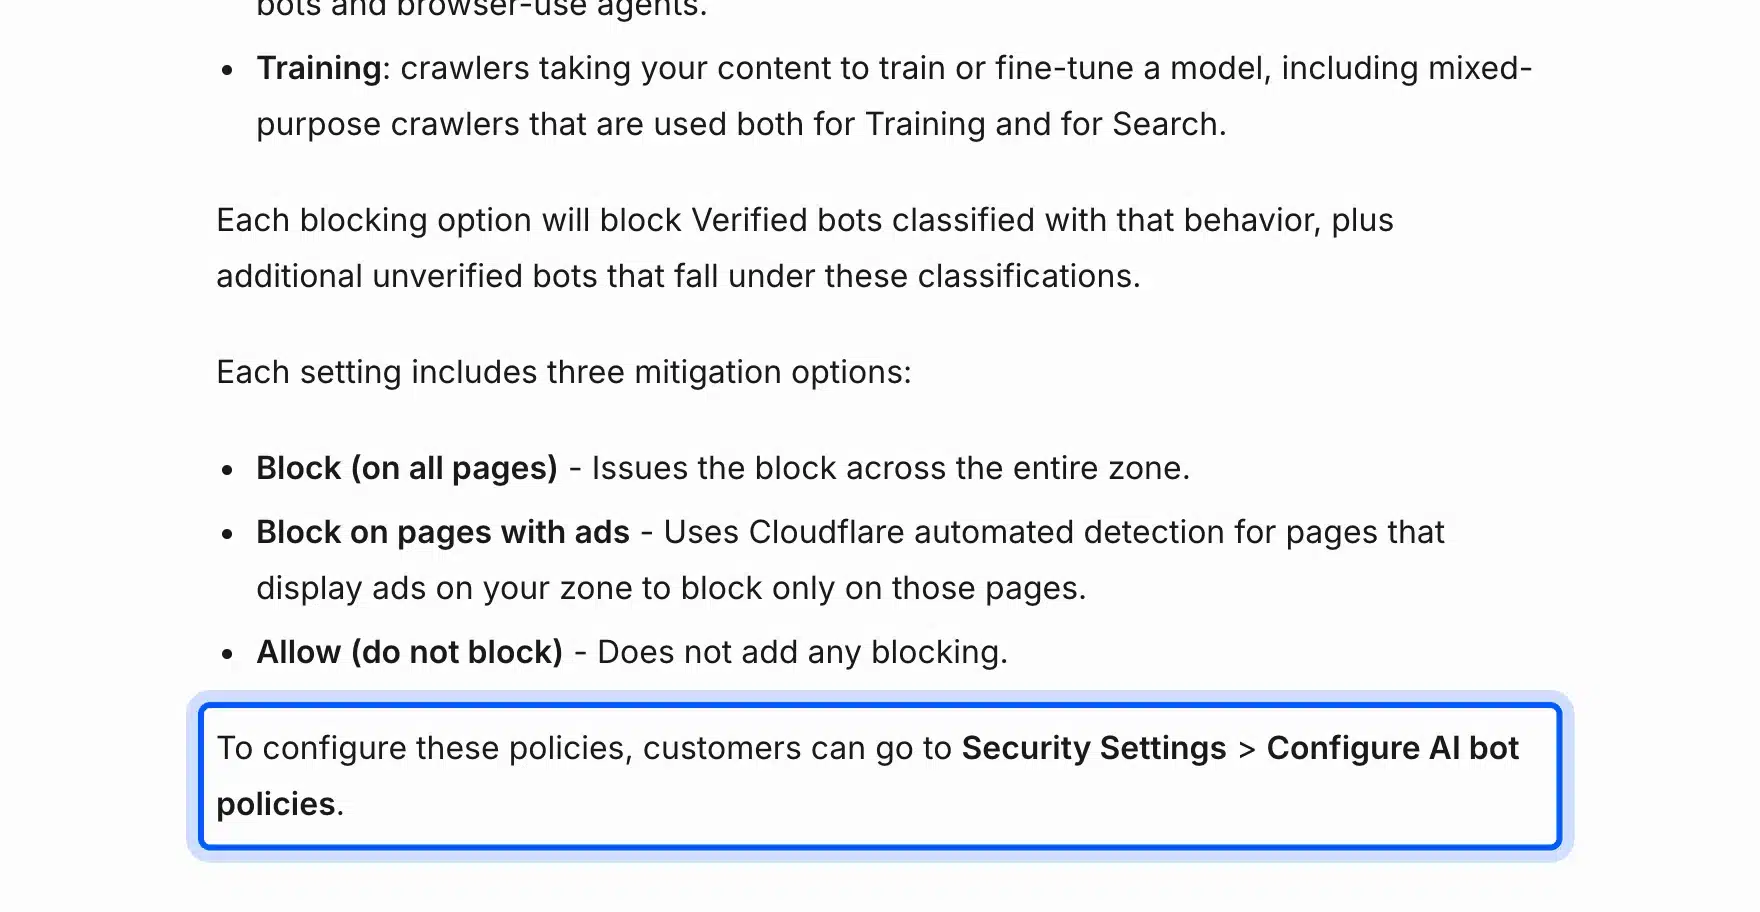
The page also lists the older Block AI bots setting as deprecating on September 15, 2026. Use the newer policies page.
Cloudflare’s WAF documentation covers the request cap rules. Plan limits differ. Read the current page for your plan before you rely on them.
These settings apply to a domain that is live on Cloudflare. They cannot run on a local test site. We describe them from Cloudflare’s documentation.
Server rules and bot policies need care. A wrong rule can lock out real visitors or search engines.
Our WordPress security checklist covers the basics first. Our WordPress security services include a review of this kind of setup.
6. Keep a Self-Referencing Canonical Tag
A canonical tag tells search engines which URL is the original. Google calls the canonical link element a strong signal. It recommends a self-referential canonical on the canonical page itself.
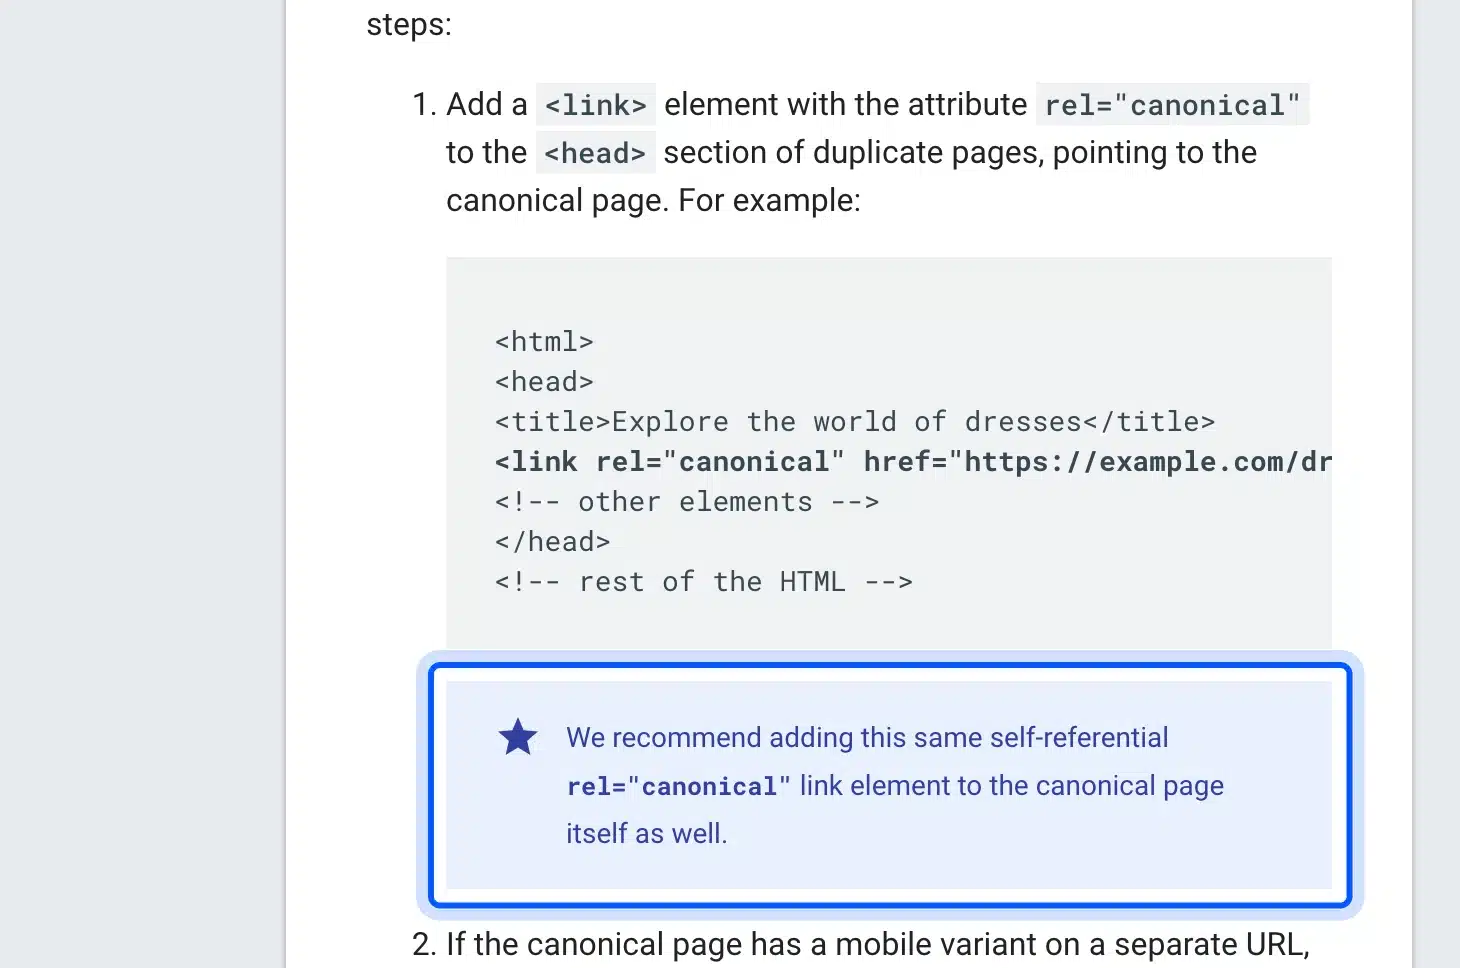
WordPress adds a canonical link to single posts. On our test site the post source held one line with the post address. If you run an SEO plugin, check that it keeps the tag.
Be honest about the limit. A scraper that copies your HTML can remove the tag. The tag helps when a copy keeps it, and it does nothing when the copy strips it.
How Do You Get a Copied Post Removed?
You get a copied post removed by contacting the owner first and then the host and Google. Keep proof of your original and file a notice for each copied URL. Google’s form asks for the exact page address of the content.
Write the owner email in plain words. Name your post and its URL, name the copy and its URL, and ask for removal by a date. A calm message gets more replies than an angry one.
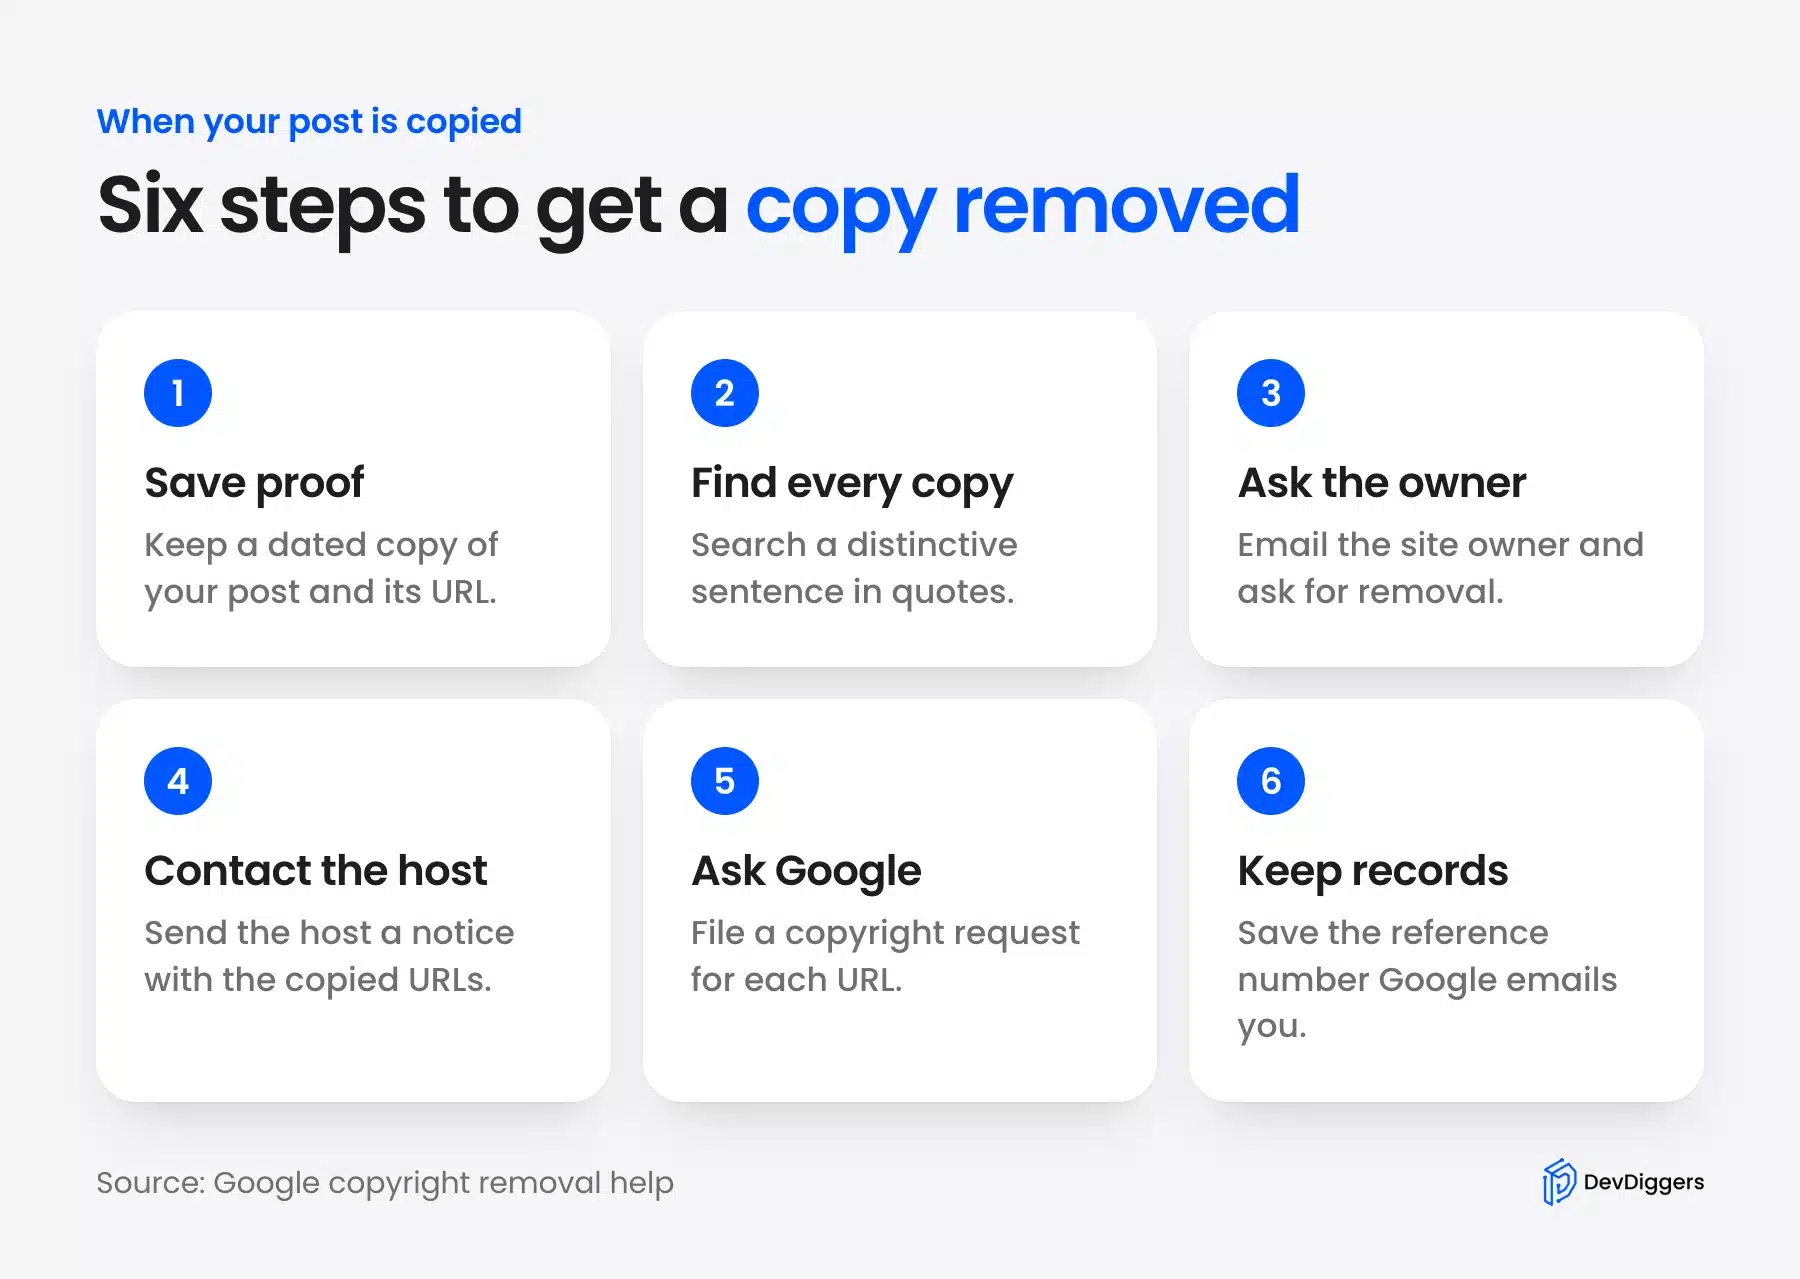
Work through these steps in order:
- Save proof: Keep your post’s URL and publish date, plus a dated copy of the text.
- Find the copy: Note every URL that holds your text, because each needs its own notice.
- Ask the owner: Send a short email with both URLs and ask for removal.
- Contact the host: If the owner ignores you, send the hosting company a removal notice.
- File with Google: Use Google’s copyright removal form and enter the specific URL of each copy.
- Keep the reference number: Google emails a confirmation and a reference number.
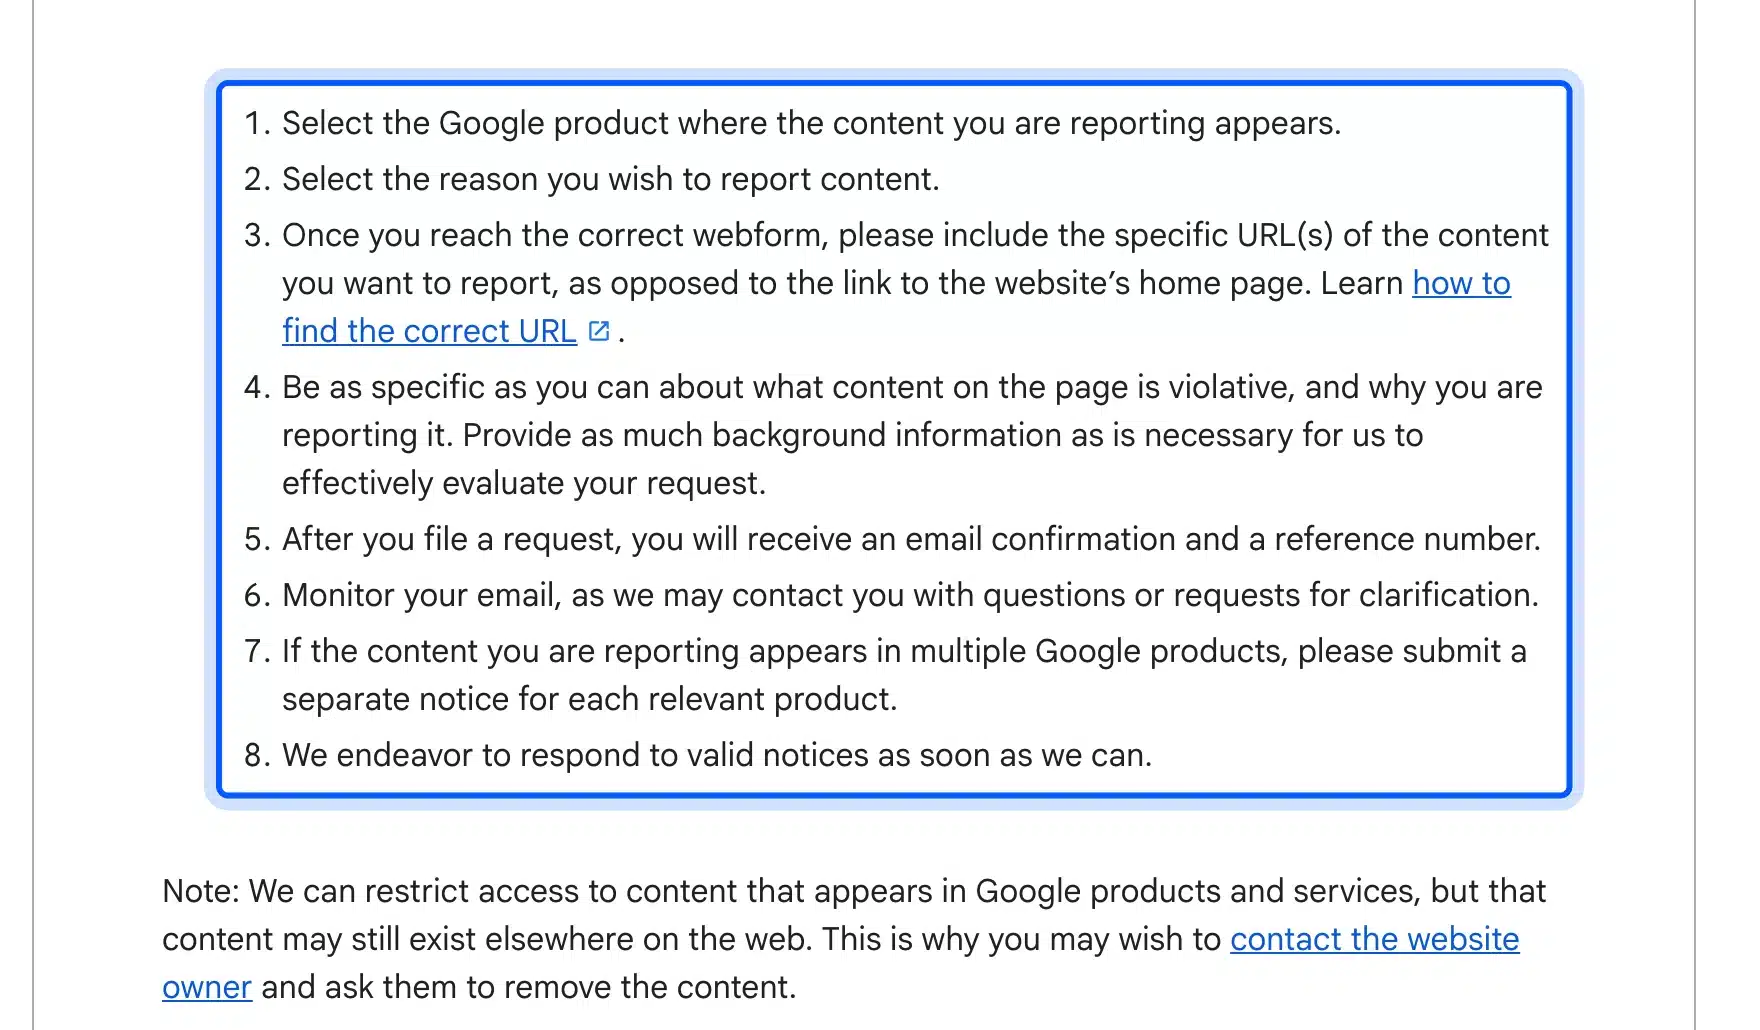
Google states that it will review the material and consider blocking, limiting or removing access. It also notes that the content may still exist elsewhere on the web.
That is why steps 3 and 4 come first.
A removal request is a legal document. Only file one for content you own.
Can You Stop Content Scraping Completely?
No, you cannot stop content scraping completely. You can raise the cost of copying your site a great deal for the people who want it. Every defense above stops one type of scraper and misses the other types that a determined copier can still use.
Layer them and expect a few copies to get through.
Browser scripts such as right-click blockers do nothing against a bot that reads your raw HTML. They run only in a browser. They slow a person who copies by hand and nobody else.
Plugins that disable copying work the same way. They add a script to the page, and a bot that never runs scripts never meets them.
| Defense | Feed scrapers | Honest bots | Disguised bots |
|---|---|---|---|
| Feed excerpts | Stops full copies | No effect | No effect |
| Feed link back | Adds a link to copies | No effect | No effect |
| robots.txt | No effect | Asks them to stop | No effect |
| Server user agent rule | No effect | Blocks named bots | No effect |
| Cloudflare bot rules | No effect | Blocks by behavior | May catch some |
| Canonical tag | No effect | No effect | Lost if stripped |
Start with the cheapest rows. The feed excerpt, the link back and the robots.txt rules each remove a route without risking real visitors. Add server and edge rules after you have read your logs.
The table summarizes the tests covered above. The Cloudflare row comes from Cloudflare’s documentation and was not run on our test site. Our WordPress care plan guide explains how ongoing monitoring can keep these rules current.
Conclusion
To prevent content scraping on WordPress you need layers. Start with the feed setting and the link back because they cost nothing. Add robots.txt rules for the training bots you want to refuse.
Use server or Cloudflare rules for bots that ignore requests. Keep proof of every post so a removal request takes minutes.
Check your logs once a month and adjust the rules. A managed setup also works if you prefer to hand it over.
Frequently Asked Questions (FAQs)
Q1. How do I protect my website from scraping?
Use layers to prevent site scraping. Show excerpts in your feed, add rules for known bots and keep proof of your original posts. No method stops every scraper, and each layer removes a type of copy.
Q2. Does a right-click blocker stop content scraping?
No. A right-click script affects only a person in a browser. A bot never loads the script.
Q3. Does blocking GPTBot remove my site from ChatGPT answers?
No. OpenAI’s crawler documentation says GPTBot relates to training and OAI-SearchBot surfaces sites in ChatGPT search. Sites opted out of OAI-SearchBot will not be shown in search answers.
Q4. Does Google-Extended affect my Google rankings?
No. Google’s crawler documentation says Google-Extended does not impact a site’s inclusion in Google Search. It also says the token is not used as a ranking signal.
Q5. Can I stop scrapers by blocking IP addresses?
An IP rule suits one noisy address. Anthropic’s support article advises against blocking its crawlers by IP because they may then fail to read your robots.txt file.
Q6. How long do robots.txt changes take to work?
OpenAI says its search systems can take about 24 hours to adjust after a robots.txt update. Other bots check the file on their own schedule. Allow a day before you test.
Q7. Should I block ChatGPT-User in robots.txt?
It will not help much. OpenAI’s documentation says ChatGPT-User covers certain actions that a person starts in ChatGPT. Because a person starts them, robots.txt rules may not apply.
Q8. Can a plugin prevent content scraping?
A plugin that only disables right-click or text selection stops casual copying by hand. For bots you need server or edge rules, such as the user agent rule and Cloudflare policies covered above.




